 InCue
Chapter 5 of 23 · Updated 22 October 2026
Services & queue configuration
On this page
Before filling the service form
A service means one kind of work your business offers: Consultation, Haircut, Sample collection or Vehicle handover. Create separate services when the work, normal duration or fee is meaningfully different. A service is not a doctor/employee's name, a counter, an appointment slot or a whole business day.
Where: Merchant > Services > add/edit. Who: merchant owner. Read each field below before saving. The examples describe training businesses; choose values that match your actual work and current agreed prices.
Service Name: what the customer is choosing
Meaning: a short recognisable name for the work. Enter: General Consultation, Haircut or Vehicle handover, using your own real service names. The name must be unique within the business; changing only letter case does not make a different service.
Why / effect: customers and reception select this item on the token form. Clear names prevent the wrong fee or workflow being chosen. Do not name two different procedures only General if staff cannot tell them apart.
Check: open a fresh staff token form and customer QR page. A first-time visitor should understand which item to select without knowing your internal code.
Avg time (min): the usual time spent doing one customer's work
Meaning: how many minutes one normal service takes after work starts until it finishes. Avg means average/usual; min means minutes. This is not the time spent waiting in the queue, opening time, appointment spacing or a fee.
Exactly what to enter: a whole number of minutes, at least 1. For example, if a typical consultation starts at 10:20 and ends at 10:30, enter 10. For half an hour enter 30. Do not enter 10:30, 0.5, 600 seconds or the number of customers per hour. The new-service form initially shows 15; review it rather than leaving it automatically.
How to decide: observe several ordinary visits. Five durations of 8, 10, 12, 9 and 11 minutes total 50 minutes; 50 divided by 5 visits is 10, so 10 is a reasonable starting estimate. Exclude the customer's time waiting before Start when deciding this value.
Why / effect: Smart ETA needs an initial estimate of the work in front of the next customer. Too small a number can promise turns too early; too large a number can make a short queue look slow. As usable history builds, actual Start-to-Complete times and current speed can adjust the working estimate. This field does not automatically stop a service, complete a token or change its price when the minutes expire.
Common mistakes: entering the full shift, the current waiting time or an artificially short value to attract customers. A very wrong starting duration can also cause genuine long visits to be rejected as unusual learning samples.
Check: tell a colleague: “One usual Consultation takes about 10 minutes once started.” Run an agreed sample with correct Start/Complete handling and review future estimates over real operation; one sample does not establish accuracy. The Smart ETA training sections below explain the complete calculation and automation.
In simple words: “Kaam shuru hone ke baad ek customer par usually kitna time lagta hai? Wahi minutes dalo; waiting time nahi.”
Base Price (₹): the normal service fee
Meaning: the ordinary rupee price for this service before optional extras/waivers in the token quote. Enter: your normal amount, for example 200 for a ₹200 consultation; use 0 only for a genuinely free service. A negative price is not allowed.
Why / effect: selected services contribute to the token amount. Payment mode decides what is collectible now versus due later; an eligible revisit may waive earlier matching services. An emergency upgrade can add a separate charge. The token quote is therefore the place to check the final payable amount.
Common mistake: entering 20000 for ₹200, putting the emergency total here and adding it again, or confusing this price with the monthly InCue subscription. This field alone does not certify a customer tax invoice or gateway settlement.
Check: select only this service in a fresh token form and read normal, waived, extra and collectible/due amounts before generating. After a catalog change, old tokens keep their saved service/price details.
Description (Optional): help people choose correctly
Meaning: a short explanation of what this service covers. Enter: something concrete such as Routine consultation with the doctor; tests charged separately, only if that matches your policy.
Why / effect: a useful description reduces wrong selections. It does not create an extra service, automatically enforce every term in the text or configure a refund/revisit rule.
Common mistake: entering private patient details, an OTP, or a price promise different from the saved quote. Check: read the description in the service catalog/customer form where displayed and confirm staff explain the same scope.
Collect payment: Prepaid or Postpaid
Meaning: when this service's charge is intended to be collected. Choose Prepaid when collecting at token creation; choose Postpaid when settling after the service. For example, a clinic may charge consultation at reception; a service centre may collect after inspection.
Why / effect: the quote separates the amount to collect now and the amount still due. Zero collectible now on a Postpaid token does not mean the whole service is free. Zero because of a confirmed revisit waiver is a different reason.
Common mistake: pressing Generate and treating it as proof of money in the bank. Prepaid handling and actual online gateway settlement must still be confirmed through their respective flow. Check: compare one Prepaid and one Postpaid sample quote without making an unintended real charge.
Emergency priority and extra emergency charge
Meaning: an explicitly offered priority option for the service, with a separate extra fee where configured. Enable it only if your real operating policy permits that priority.
Enter: the extra rupee amount, not the combined total. Example: normal ₹200 plus extra ₹100 gives ₹300 before other quote adjustments. If ₹300 is the intended total, do not enter ₹300 as the extra on a ₹200 base.
Why / effect: a selected emergency token is treated ahead of ordinary waiting work in the ETA ordering and can increase other visitors' waits. It is an operational priority flag, not medical triage or clinical decision support. A revisit waiver of a matching normal service does not automatically waive an emergency upgrade.
Check: staff should select priority only when agreed, review the extra in Token Preview and understand why the normal token-number order may be interrupted.
Save and verify the complete service
Use Confirm & Save once. Reopen the item and check name, usual minutes, price, payment mode and priority. Then open a fresh token form; an old open form may contain stale catalog data. Merely typing into the dialog is not a saved change.
| Example business | Sensible starting explanation | What not to enter as duration |
|---|---|---|
| Clinic | Consultation usually takes 10 working minutes; ordinary fee ₹200 Prepaid. | The patient's 45-minute wait or the doctor's eight-hour shift. |
| Salon | Haircut usually takes 20 minutes; hair spa is a different service if its work/time/price differs. | A 15-minute calendar slot just because appointment starts are spaced by 15 minutes. |
| Diagnostic reception | Sample collection usually takes 5 minutes of counter work. Explain separately when the report is ready. | Six hours of laboratory processing if this queue only handles a five-minute sample-collection desk. |
| Service centre | Vehicle handover may take 5 minutes after repair work is genuinely completed; repair is a different service if separately queued. | Five minutes for a repair that normally occupies a worker for 90 minutes. |
These durations are examples to teach the meaning, not industry standards or promises. Smart ETA also uses real service history, current workload, compatible counters, breaks and schedule; the number alone cannot describe the entire business.
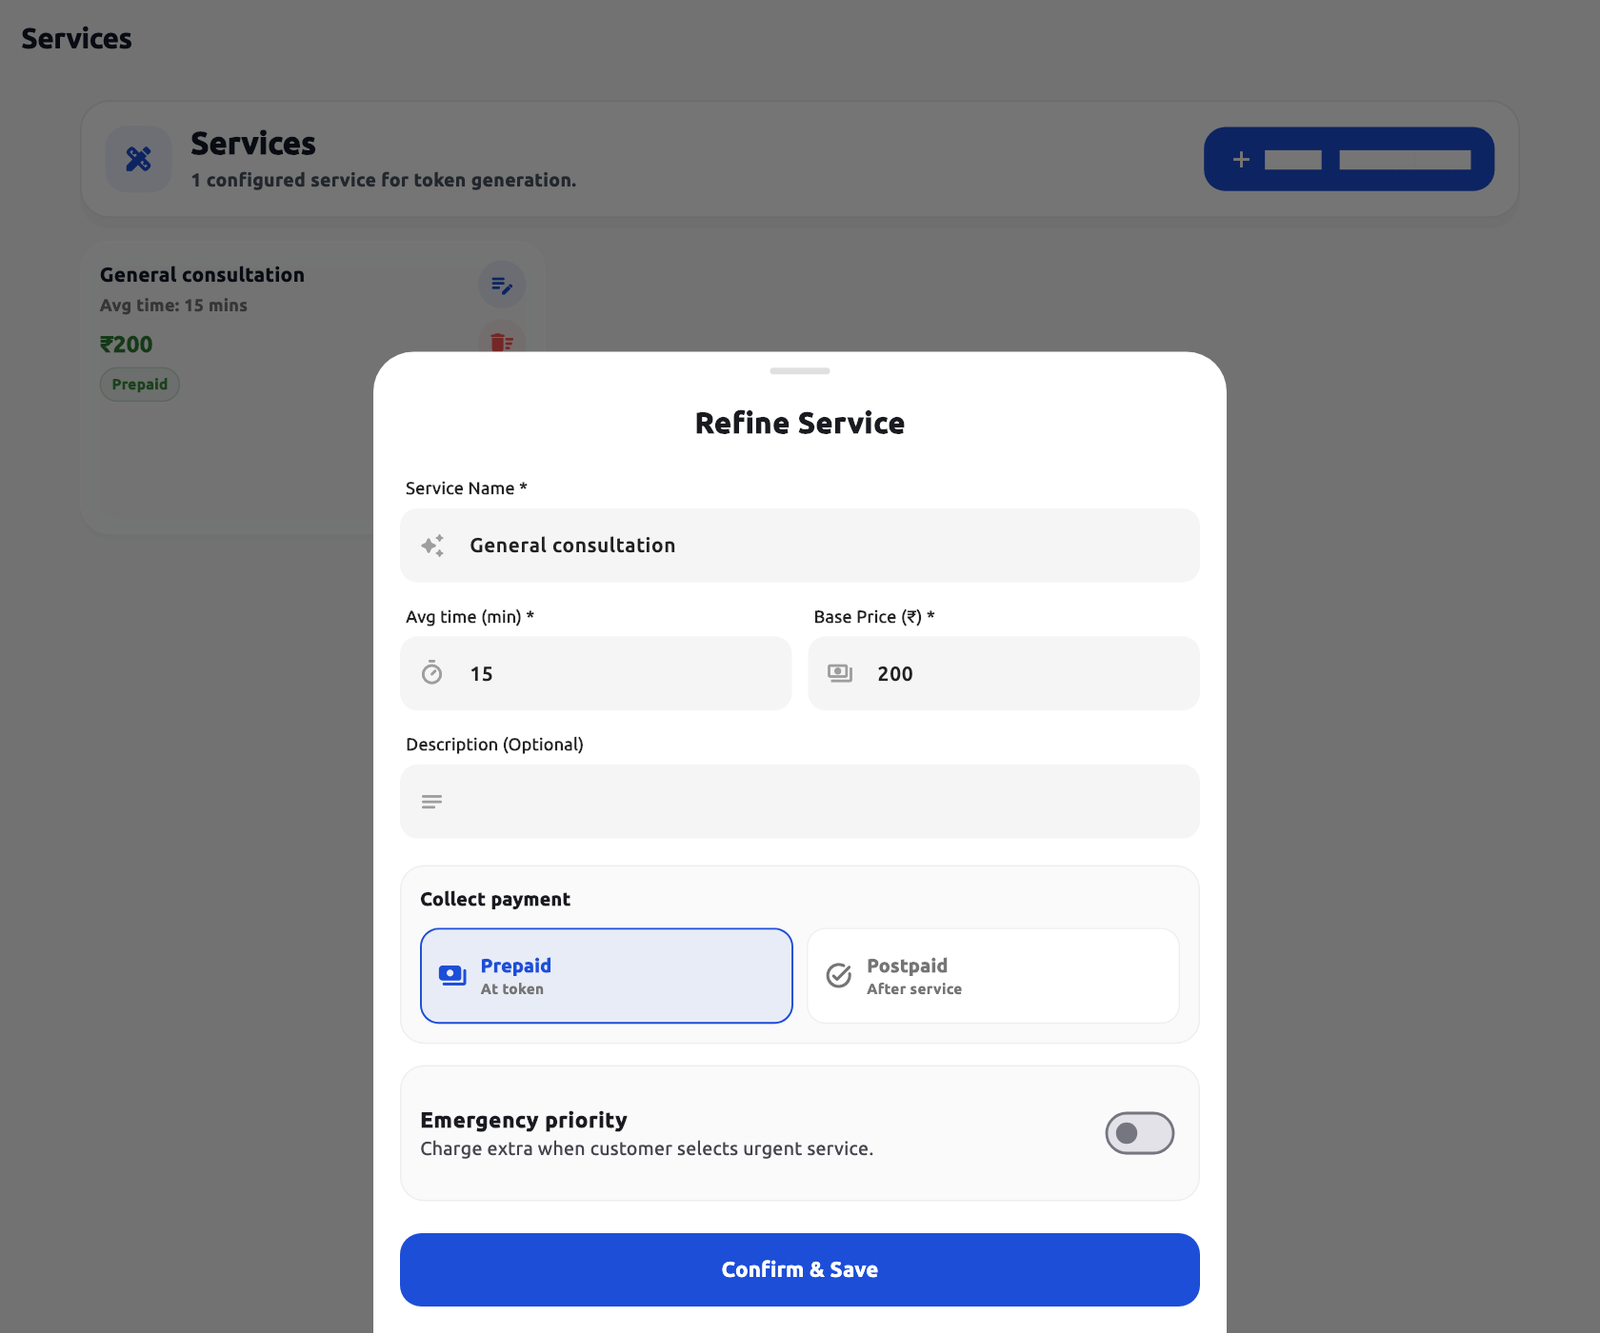 Service editor. Actual application interface with synthetic example data.1.Service identity and expected minutes.2.Payment mode and optional priority charge.
Edit, remove or make a service unavailable
Open the service card's edit action, change the relevant fields, confirm and verify a fresh form. The visible delete action uses Delete Service confirmation. The inspected backend implements this as a status toggle/soft removal, not destruction of past token records. Do not repeatedly press delete to try to permanently erase history. If the current app does not expose reactivation, ask support to restore the catalog item rather than recreating conflicting names.
Inactive services should not be offered for new token generation. If an old form still contains an item, reload it; the server can reject an item or price that has changed.
Smart ETA: understand the estimate
The following is the complete trainer lesson. Owners can read the everyday examples first; the technical notes explain source limits and server configuration.
Start with these three different times
Imagine a patient reaches reception at 10:00, starts consultation at 10:20 and finishes at 10:30.
| Term | Plain meaning | In this example |
|---|---|---|
| Service duration / Avg time (min) | How long one customer's actual work usually takes after it starts. | 10 minutes, from 10:20 to 10:30. |
| Waiting time | Time before that person's service starts. | 20 minutes, from arrival at 10:00 to Start at 10:20. |
| ETA / expected turn time | An estimate of when service can begin, based on the queue and available working time. | Around 10:20, or an estimated waiting range. |
ETA means Estimated Time of Arrival in general usage. In InCue's queue screens, read it as estimated time until your turn/service can start. It is not the time by which the work will be finished, an appointment guarantee or the amount to collect.
Trainer's line: “Avg time mein ek customer ka kaam shuru hone se khatam hone tak ka usual time dalo. Line mein khade rehne ka time mat dalo. ETA batata hai bari lagbhag kab aayegi.”
Why the service duration matters
When the business has little usable history, InCue needs a sensible starting estimate. Enter the usual working time for one service: for example Consultation 10 minutes, Haircut 20 minutes, or Vehicle handover 5 minutes. These are teaching examples, not recommended times for every business.
Watch several ordinary visits and estimate the typical time from Start to actual finish. If five consultations take 8, 10, 12, 9 and 11 minutes, their simple average is 10 minutes. Enter 10, not 10:00, 600, the doctor's full shift, a day's total workload or the patient's current wait. The current service form accepts whole minutes, at least 1; a new form starts at 15.
If a usual ten-minute consultation is saved as 30, early estimates can become too late. If a normal thirty-minute repair check is saved as 5, estimates can be too optimistic and unusually long samples may be excluded from learning. Start with an honest normal duration; do not deliberately shorten it to make the queue look fast.
Quick check: open Services, read each active service name and its Avg time aloud: “One normal [service] takes around [minutes] after we start.” If that sentence sounds wrong, review the value.
What Smart ETA considers, in everyday language
The engine builds an estimate of the work ahead of a waiting token. It considers the selected service(s), usable completed-visit timings, recent operating speed, called/serving work, queue priority/order, counter compatibility/capacity, and the saved business schedule.
- Choose a working duration for each service. With no usable history it falls back to the configured duration. With history it gives more weight to recent completed work, while retaining part of the configured value.
- Check how today is moving. Enough valid recent completions can make the working estimate faster or slower than its historical baseline.
- Account for work already called or serving. A called person still needs to arrive and receive the service. A serving person still occupies a counter; elapsed time helps estimate what remains.
- Place waiting work ahead on eligible counters. Emergency-priority work is considered first, then token number order. Different compatible counters can work in parallel; a worker who cannot provide the selected services is not interchangeable with one who can.
- Apply operating time. If the work crosses a saved lunch break or closing time, the expected turn can move to the next working interval.
- Show an estimate with uncertainty. A range communicates that real services vary. A longer queue or limited history can produce a wider range.
This is an estimate from recorded operations, not a sensor watching the doctor, mechanic or customer. It cannot know an unrecorded absence, a conversation after work, a missing staff member still marked available, or an unexpected job complication until available data changes.
A clinic example you can explain at reception
Assume one counter, no break, no emergency work, no speed/no-show adjustment, and a working service estimate of 10 minutes. These assumptions isolate the arithmetic; a live account can give a different range.
| Work before your token | What contributes to the wait |
|---|---|
| One consultation Serving for 4 minutes | About 6 minutes of estimated work remain, plus the engine's 1.5-minute transition allowance. |
| One ordinary token Waiting ahead | About 10 minutes of work plus another 1.5-minute transition allowance. |
| Your token | Its estimated wait is about 19 minutes, before display rounding, confidence range and business-time adjustments. Your own consultation duration is not added to the wait for it to start. |
If reception completes the active consultation earlier, the next calculation can reduce waiting estimates. If a more complex case continues well past the usual duration, the engine can allow additional remaining time rather than claim the counter is already free. Complete should therefore mean work actually ended.
What to tell the patient: “This is an approximate turn estimate. It can move if an earlier consultation takes longer or an urgent case is added. Keep your token and follow the live status.” Do not promise an exact minute from a range.
Two counters, different services and long jobs
Two genuinely available haircut workers: waiting jobs can be distributed across compatible capacity. Two workers can reduce the wait, but not always by exactly half because jobs have different lengths and one worker may already be busy.
Clinic doctor and lab desk: a lab worker is not a second consultation counter just because both are online. Map their real services. In service-aware routing, a counter must cover the token's full selected service set. Where no full matching counter mapping is available, the estimator can fall back to configured virtual capacity; that fallback is an estimate, not proof a real eligible worker is available.
Service centre repair plus washing: multiple selected services contribute to estimated work. The system does not automatically prove that repair and washing happen in parallel. Use service definitions that describe the work you actually run. A week-long workshop job should not be modelled as a five-minute quick counter service just to shorten the displayed queue.
Held / Cancelled / No-show: these do not occupy an ordinary waiting position in the live waiting-list simulation. A held customer's later return can affect the queue again. No-show probability adjustment and actually marking a token No-show are different things; see below.
Lunch, closing time, Pause and Resume
Saved break example: it is 12:50, the work ahead needs 30 working minutes, and lunch is 13:00-14:00. There are 10 working minutes before lunch and 20 after it, so the central expected turn is around 14:20, before any range variation.
Small spillover exception: the schedule helper allows up to 10 remaining working minutes into an ordinary break if some work in that calculation was already consumed before the break. For example, 12 minutes of work from 12:50 can estimate 13:02 instead of jumping past a one-hour lunch. This models a short wrap-up, not a promise that staff will skip lunch. It does not apply when the calculation starts inside an already ongoing break, or to a configured hard scheduled pause. Ask reception if the displayed turn is near a break boundary.
Closing example: a wait longer than the workable minutes left today can continue into the next selected working day. A 0-minute work backlog outside an open interval can still be scheduled to a later opening. Correct hours matter even with an apparently empty queue.
Manual Pause: there may be no known end time, such as the doctor being called away. The ETA formatter switches to a paused message, and optional ETA WhatsApp messages are suppressed while paused. Other screens may still retain their last number or show their own paused state. Do not tell customers a live countdown proves work is progressing during a pause.
Resume: the engine has a short return-to-work allowance: source defaults add 3 minutes during the first 5 minutes after Resume. It allows staff time to get back rather than assuming immediate service. This is a server rule, not a merchant slider verified in the app.
Closing intake is different: Accept walk-ins controls new intake; Pause concerns the current queue. Neither button is a substitute for saving the real daily hours and lunch breaks.
What changes automatically, when and why
| Trigger / condition | Automatic behaviour | What the operator must still do |
|---|---|---|
| Token created, called, started, completed, cancelled, marked No-show or updated through the normal queue paths | Snapshot invalidation schedules a fresh ETA/queue sync. The source default groups nearby events with an approximately 800 ms delay before rebuilding/broadcasting. | Check that the action succeeded and the screen is connected; this delay is not an end-to-end delivery guarantee. |
| Tracking/API or queue snapshot requests an updated estimate | ETA can be calculated again from current queue data, reusing cached profiles. | Refresh/reconnect when the interface reports an old connection; no universal per-second server update is promised. |
| Valid visits are completed | Historical profiles and recent-speed estimates can change as caches refresh. | Record Start and Complete at the real times; learning is not immediate after every click. |
| Serving work exceeds its expected duration | Remaining-time logic allows for an overrun, increasing with a significant overrun up to a cap. | Verify the worker is still serving; correct a forgotten status instead of relying on ETA to close it. |
| Queue paused / resumed | Paused wording and notification suppression; short transition allowance after resume. | Resume only when work can restart. |
| Optional ETA alert job runs and a waiting token qualifies | It may send one selected approaching-turn, delay, early or “next” message, subject to gates and budget. | Keep wallet/provider/contact details usable; a timer tick is not proof of message delivery. |
| Assignment mode Auto, eligible waiting work and a compatible available counter | Assignment routines can claim a free counter and call a token when invoked by supported workflow events. | The worker still starts actual service; Auto is not permission to leave stale availability. |
| Auto-complete on next enabled in a supported reception flow, then operator advances | The earlier eligible active work can be closed as part of advancing. | Confirm work and payment are actually finished before Next. This is action-triggered, not a duration timer. |
| Backend automatic no-show explicitly enabled for that merchant, and a Called token remains unanswered | The no-show job can close it and attempt auto assignment of later work where allowed. | This opt-in is backend configuration, not a verified merchant-accessible setting. Keep ordinary manual No-show handling clear. |
| Eligible appointment reaches its queue-conversion condition | Appointment conversion can produce a Waiting token; normal queue/TV updates follow the token path. | Confirm the converted token and appointment reference; conversion is not the same as the customer arriving or service starting. |
Automatic no-show is not the two-minute called allowance
The ETA calculation allows 2 minutes for a called customer to approach, then includes the service and transition work. This two-minute allowance does not itself mark the person absent.
The separate no-show job has a source default of 10 minutes since Called, checked on a default two-minute schedule, and requires the merchant's explicit backend opt-in (autoNoShowEnabled, default false) as well as the server job being enabled. Therefore it is neither on for every merchant nor guaranteed to run at the exact ten-minute second. It does not automatically mark every old Waiting token absent. Do not tell a customer “after two minutes your token is cancelled.”
Appointment conversion is not an exact appointment-time promise
The source includes an every-minute eligible-appointment job and an on-demand catch-up before ordinary token creation. It compares the projected queue serving time with the appointment start, with a past-due safety path. Only eligible active appointments are candidates; completed/cancelled/already-converted records do not become new tokens again through the ordinary conversion path. Failed conversion has bounded attempts and needs attention if it cannot recover.
This is a separate conversion scheduler using its queue projection; it is not a promise that every Smart ETA range, calendar slot and WhatsApp time is identical. Staff should inspect the generated token when checking in a customer. Do not create a second walk-in solely because the appointment view has not refreshed.
WhatsApp: when a waiting customer may hear from InCue
First understand calculation versus communication: the displayed estimate can change without a new WhatsApp. Message selection deliberately avoids sending on every small change. It can be skipped for a closed/paused token, recent messages, uncertain shifts, exhausted optional budget, contact/withdrawal restrictions, wallet or provider failures.
Deployment configuration read on 22 October 2026: the ETA alert job is scheduled every 5 minutes. The deployed ETA/notification source hashes matched the source reviewed for this guide. The following values are configuration evidence, not a promise of scheduler uptime, successful delivery, a per-account grant or a permanent timing contract. They are server controls; this guide does not invent Merchant settings for them.
| Original estimated wait | Planned normal reminder window in the inspected deployment |
|---|---|
| More than 180 minutes | Around 60 minutes remaining. |
| More than 120, up to 180 minutes | Around 30 minutes remaining. |
| More than 20, up to 120 minutes | Around 15 minutes remaining. |
| Up to 20 minutes | Around 10 minutes remaining. |
Each reminder window has a configured plus/minus 4-minute tolerance, requires a positive remaining wait, and can be missed if work changes suddenly or a job/check cannot run in that window. The plan is based on the original estimate, not a request to send all four reminders to everyone. Source fallback for the long-wait boundary is 60 minutes; the inspected deployment overrides it to 120. Do not copy the source fallback as the active deployment value.
You're next: considered first when no eligible waiting work is ahead and ETA is 25 minutes or less, subject to cooldowns, deduplication and budget. Being first in Waiting does not mean a busy counter has finished; this message does not call or start the token.
Delay / earlier-turn changes: small variations can be silent. The inspected deployment uses a 20-minute delay threshold and a 15-minute earlier-turn threshold, together with a 10-minute smoothing/range buffer, at least 15 minutes useful notice, confidence and decision checks. An extremely large early jump above the source's 90-minute plausibility limit is suppressed. A large numerical change alone does not guarantee a message.
Avoiding repeated messages: the inspected deployment has a 10-minute optional-notification cooldown and a separate 3-minute conflict window. Normal reminders, early updates and delay updates have additional duplicate/sequence rules. After a delay, a final around-15-minute reminder may qualify; a routine final reminder after an early update is disabled in this deployment. After an ordinary reminder, the normal selection path does not promise every later shift update; “You're next” has its own earlier priority check.
Budget: source/configured maximum is 6 customer messages per token in the ETA budget policy, with a target of 4. That is an internal policy target/cap for the tracked flow, not a bundle promise or a guarantee of four deliveries. Optional ETA sends reserve room for later core service/feedback events. Appointment, transfer and other message classes have their own paths; do not treat this number as a universal global cap on every communication. A failed provider attempt does not intentionally consume a successful-send slot permanently.
Called / serving / completed: ETA waiting notifications close when the token leaves the relevant waiting phase or the serving update closes the notification state. Event-based call/serving/feedback messages are separate. A TV announcement uses its own settings and the TV's unlocked audio, even if WhatsApp is disabled.
Technical notes: what the current implementation actually does
These details are for administrators and developers. Owners can operate correctly using the examples above. Tuning values below are source defaults unless explicitly labelled deployment overrides; they are not additional customer-editable fields.
Historical duration and current speed
- Historical profiles inspect up to 120 recent completed tokens within 90 days of the merchant, with a real
serviceStartedAt. Samples below one minute are excluded. A sample abovemax(3 minutes, 3 x the configured service duration)is excluded for that service. - The service baseline is 60% average of up to the latest 10 usable samples + 30% average of up to the latest 30 + 10% configured duration. The sets overlap intentionally; it is not 40 separate visits. With no usable history, use the configured fallback. Missing-service/global fallback can be 15 minutes.
- A historical multi-service token's entire elapsed visit can be attributed to each included service. This is a limitation: it does not measure separate per-service stopwatch segments and can overstate combined work. The live-speed per-service attribution is stricter and uses single-service tokens only.
- Today's speed compares actual versus baseline duration for up to 50 completed tokens in the last 60 minutes, within today's date, needing at least 3 usable samples. Valid actual elapsed time is 1 minute to 4 hours. A per-service factor wins with enough single-service samples; otherwise the global factor applies. The factor is clamped to 0.5-1.8 times baseline, so an outlier cannot scale it without bounds.
- Historical profiles cache for about 5 minutes; speed profiles for 60 seconds. Config/service/queue invalidation paths and cache availability can affect freshness. A newly completed visit is not a guarantee of an immediate visible recalculation of the learned profile.
Active work, priority and uncertainty
- Called work contributes its estimated service time plus 2 minutes to approach and a 1.5-minute transition. That arrival allowance is not a no-show timeout.
- Serving work uses elapsed time and a minimum remaining allowance (source defaults 3/5/10 minutes for short/medium/long work). When overdue, a ramped/proportional extra estimate is capped at twice estimated duration. It is deliberately not a stopwatch countdown to guaranteed zero.
- Waiting contributions include service duration plus 1.5 minutes transition. Emergency tokens sort ahead of ordinary work; otherwise token number sorts ascending. The target's own service duration is not added to its pre-service waiting time.
- Active service-aware counter mappings include linked active busy staff, or online/available staff accepting work, with compatible services. Where a matching full-service pool is unavailable, configured concurrent/virtual capacity can be used; it does not prove physical availability. Increasing a capacity number must not replace correct staffing.
- No-show history uses completed/no-show outcomes in a 30-day lookback, at least 10 outcomes and a default 40% probability cap. Its expected-work discount applies only to ordinary waiting entries from the third eligible position onward, not the first two or emergency work. It does not change those tokens' real statuses or declare any particular customer absent. The rate cache is 5 minutes.
- Confidence is a heuristic: at least 20 usable samples across the inspected service profiles with fewer than 10 ahead can be high; fewer than 5 samples or more than 20 ahead produces low confidence. Otherwise it is medium. Paused queues force low confidence. This is not a certified statistical confidence interval.
- Ranges use 5-minute buckets by default. Width is at least 5/10/15 minutes for high/medium/low confidence, and can widen with the wait (12%/20%/35% rounded to buckets). Business schedule adjustment applies to the range endpoints. Notification smoothing may keep the last displayed range while a new raw value remains within it; ordinary live queue overlays do not necessarily use that notification-state smoothing.
Sources and boundaries for maintainers
Reviewed paths: services/queue.service.js (duration profiles and intake projection), services/eta.service.js (live simulation/ranges), services/queue_snapshot.service.js (ETA attachment and sync), services/eta_notification.service.js (gates and message policy), services/auto_skip.service.js, services/staff_assignment.service.js, services/appointment_auto_generate.service.js, and the related jobs/scheduler. Server configuration was inspected with an allowlist of non-secret timing flags; no customer records or settings were changed for this training revision.
The intake/appointment projection and live existing-token engine are separate code paths. Do not promise identical estimates before issuance and after the token joins the live queue. The accepted token's current live status and tracking estimate should be explained to the customer.
Train your team in five minutes
- Ask: “Does Duration mean time in line or time doing the work?” Correct answer: doing one customer's service after Start.
- Give a ten-minute example with two people ahead. Ask why the wait can be longer than ten minutes and why two compatible workers can help.
- Ask staff to demonstrate Call, then Start, then Complete and explain the physical moment each represents. Do not trigger a real charge just for a demonstration.
- Explain the lunch example and when to Pause versus close intake.
- Ask: “If ETA changes, must a WhatsApp be sent?” Correct answer: no; timing, material change, confidence, cooldown, budget and delivery conditions apply.
If ETA looks wrong: check the token's status, current connection, service durations, forgotten Serving work, real staff availability/service mappings, saved hours/breaks and pause state. Confirm whether you are reading waiting time or expected clock time. Record the token/reference, IST time and a redacted screen if the discrepancy remains. Do not shorten every service duration or mark unfinished work Complete to force a pleasing number.